Why multimodal AI matters now: the problem, the promise, and what this guide delivers
It’s 2026, and the world of artificial intelligence is moving faster than ever. For many leaders and experts, keeping up with all the new AI advancements feels like trying to drink from a firehose. There’s so much information out there, it’s hard to tell what’s truly important from what’s just hype. This overload makes it tough to make smart choices about using new tech, especially when it comes to something as powerful as multimodal AI.
Multimodal AI is a big deal right now. It refers to smart AI systems that can understand and work with more than one type of data at once. Think about AI that can see pictures, hear sounds, read text, and even process video all at the same time. This is a step up from older AI that could only handle one kind of information at a time. It promises a future where AI can understand the world more like humans do, leading to truly advanced intelligence and more helpful tools. Experts are constantly surveying this complex field to keep track of the rapidly evolving landscape of generative AI for multimodal content across different data types, like text, images, and video, showing just how fast it is growing Generative AI for multimodal content: a survey with empirical and….
The promise of multimodal AI is huge. It can lead to smarter AI assistants, better ways to analyze customer feedback from different sources, and even new creative tools that combine images and text perfectly. This kind of contextual AI can pick up on subtle cues that single-mode AI might miss, making it one of the smartest AI developments we’re seeing.
This guide is here to help you cut through the noise. We will give you clear, easy-to-understand explanations about how multimodal AI works. We’ll look at the big ideas, the latest research, and what these new products actually mean for you. Our goal is to help you see the real power of this technology, so you can tell the difference between exciting breakthroughs and just talk. This way, you’ll be able to make better strategic decisions for your work or business. If you are eager to learn more about new technologies like this, you might want to consider how to unlock AI potential with a structured learning path.
Understanding these new tools can give you a real edge. To stay continuously informed with easy-to-digest daily updates, consider getting The AI Newsletter Worth Reading.
What ‘multimodal AI’ really means: architectures, modalities, and integration patterns
The last section talked about how multimodal AI can see, hear, and read all at once, just like people. But what does that really mean? Let’s break down how these smart AI systems are built, what kinds of information they use, and how they put it all together.
At its heart, multimodal AI is about teaching computers to understand different types of data, or "modalities," at the same time. Think of how you use your eyes to read this text and your ears to hear someone talking nearby. Multimodal AI tries to do the same thing. This makes the AI much smarter because it gets a fuller picture of the world, leading to more advanced intelligence.
Types of Data Multimodal AI Uses (Modalities)
Multimodal AI works with many kinds of information. Here are the most common ones you’ll hear about in 2026:
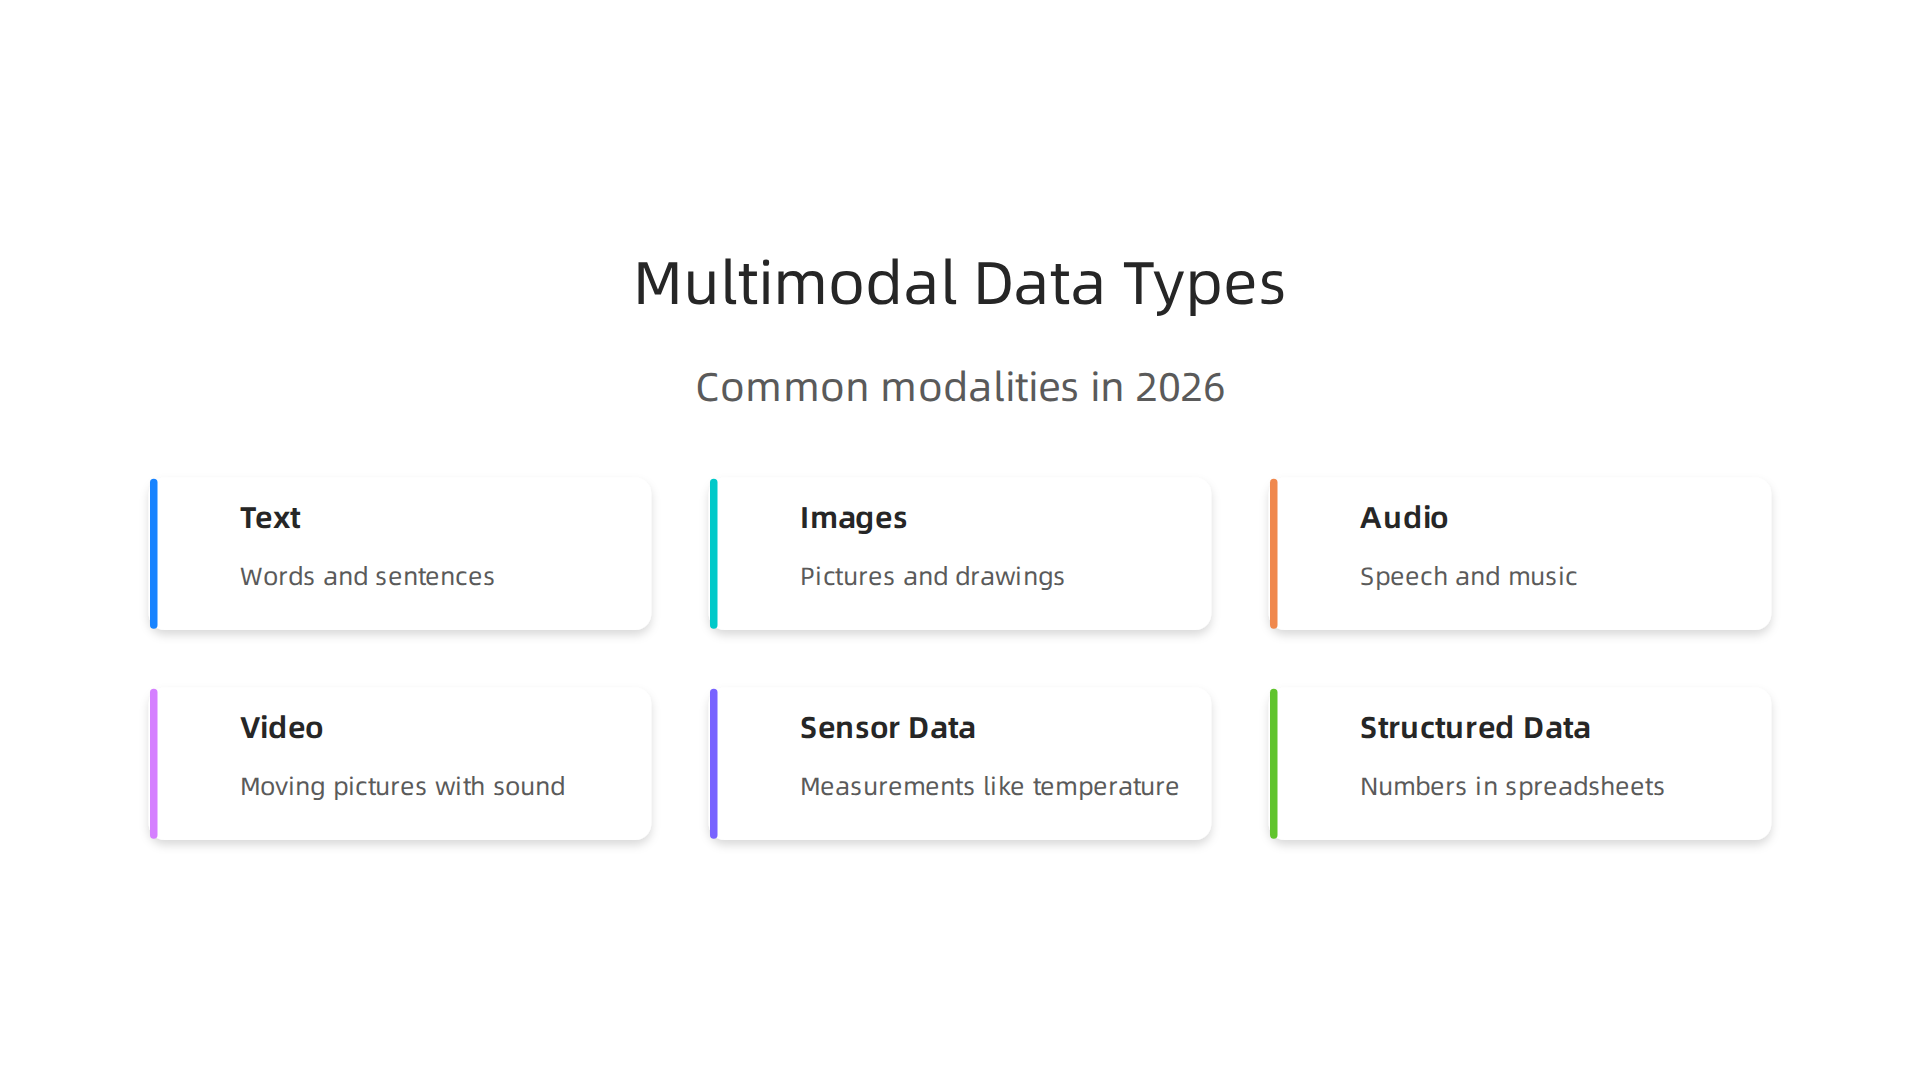
- Text: Regular words and sentences, like what you’re reading now.
- Images: Pictures, photos, and drawings.
- Audio: Sounds, speech, and music.
- Video: Moving pictures with sound. This is like combining image and audio.
- Sensor Data: Information from things like temperature sensors, GPS, or even medical devices.
- Structured Data: Organized information, like numbers in a spreadsheet or facts in a database.
For example, a multimodal AI system might look at a video (image and audio), read a description (text), and understand what’s happening better than if it only saw the video without the text. Surveys often explore how generative models handle combining these different types of information, like text, images, and video, to create new content Generative AI for multimodal content: a survey with empirical and ….
How Multimodal AI Puts Data Together (Architectures and Integration)
The way different types of data are combined is called "fusion." There are a few main ways AI systems do this:
- Early Fusion: This is like mixing all the ingredients for a cake right at the start. The AI takes raw data from different sources (like pixels from an image and words from text) and mixes them together very early in the process. This lets the AI see how different types of data relate to each other from the very beginning. However, it can be tricky if the data types are very different or noisy Multimodal Deep Learning: A Survey of Models, Fusion ….
- Late Fusion: With this method, the AI processes each type of data separately first. Imagine baking different parts of a meal in different ovens. Then, only at the very end, does the AI combine the results to make a final decision. This is often simpler to set up. It’s sometimes more accurate because each part focuses on its own data, but it might miss subtle connections between the data types.
- Unified Encoder/Decoder Approaches: This is a newer, more advanced way. It’s like having one very smart brain that can understand all the different types of data at once. These systems, sometimes called "foundation models," learn a common way to represent all the data. Then, they can switch between tasks and data types easily. This helps the AI gain truly contextual AI capabilities and is seen as one of the smartest AI developments today.
Each of these ways has its own ups and downs. Early fusion can catch small details but needs a lot of processing power. Late fusion is often easier to handle but might not be as good at understanding complex relationships. Unified approaches aim for the best of both worlds, but they need huge amounts of training data and powerful computers. For example, some studies show that while late fusion can give the most accurate results, early fusion is often faster to process Exploring Fusion Strategies for Multimodal Vision- ….
Understanding these different methods helps us see why some multimodal AI tools perform better than others, and why building them can be quite a challenge. It’s all about finding the right balance for the job at hand. Knowing how to choose the right AI models is crucial, and you can learn more about picking the right ones by exploring resources like how to choose what is the best AI for your needs.
Now that we’ve talked about how multimodal AI combines different kinds of data, let’s look at how these smart systems actually learn. It’s not magic, but it does involve huge amounts of data and clever training methods.
How Multimodal Models Learn: Datasets, Pretraining, and Transfer
The journey for a multimodal AI model to become truly useful starts with "pretraining."
This is like sending a student to a very big school where they learn many general things before focusing on a specific job. During pretraining, AI models learn to understand different types of information and how they relate to each other. This is key to building advanced intelligence.
Making Multimodal AI Smart: Pretraining Methods
There are a few main ways multimodal AI models are taught during pretraining:
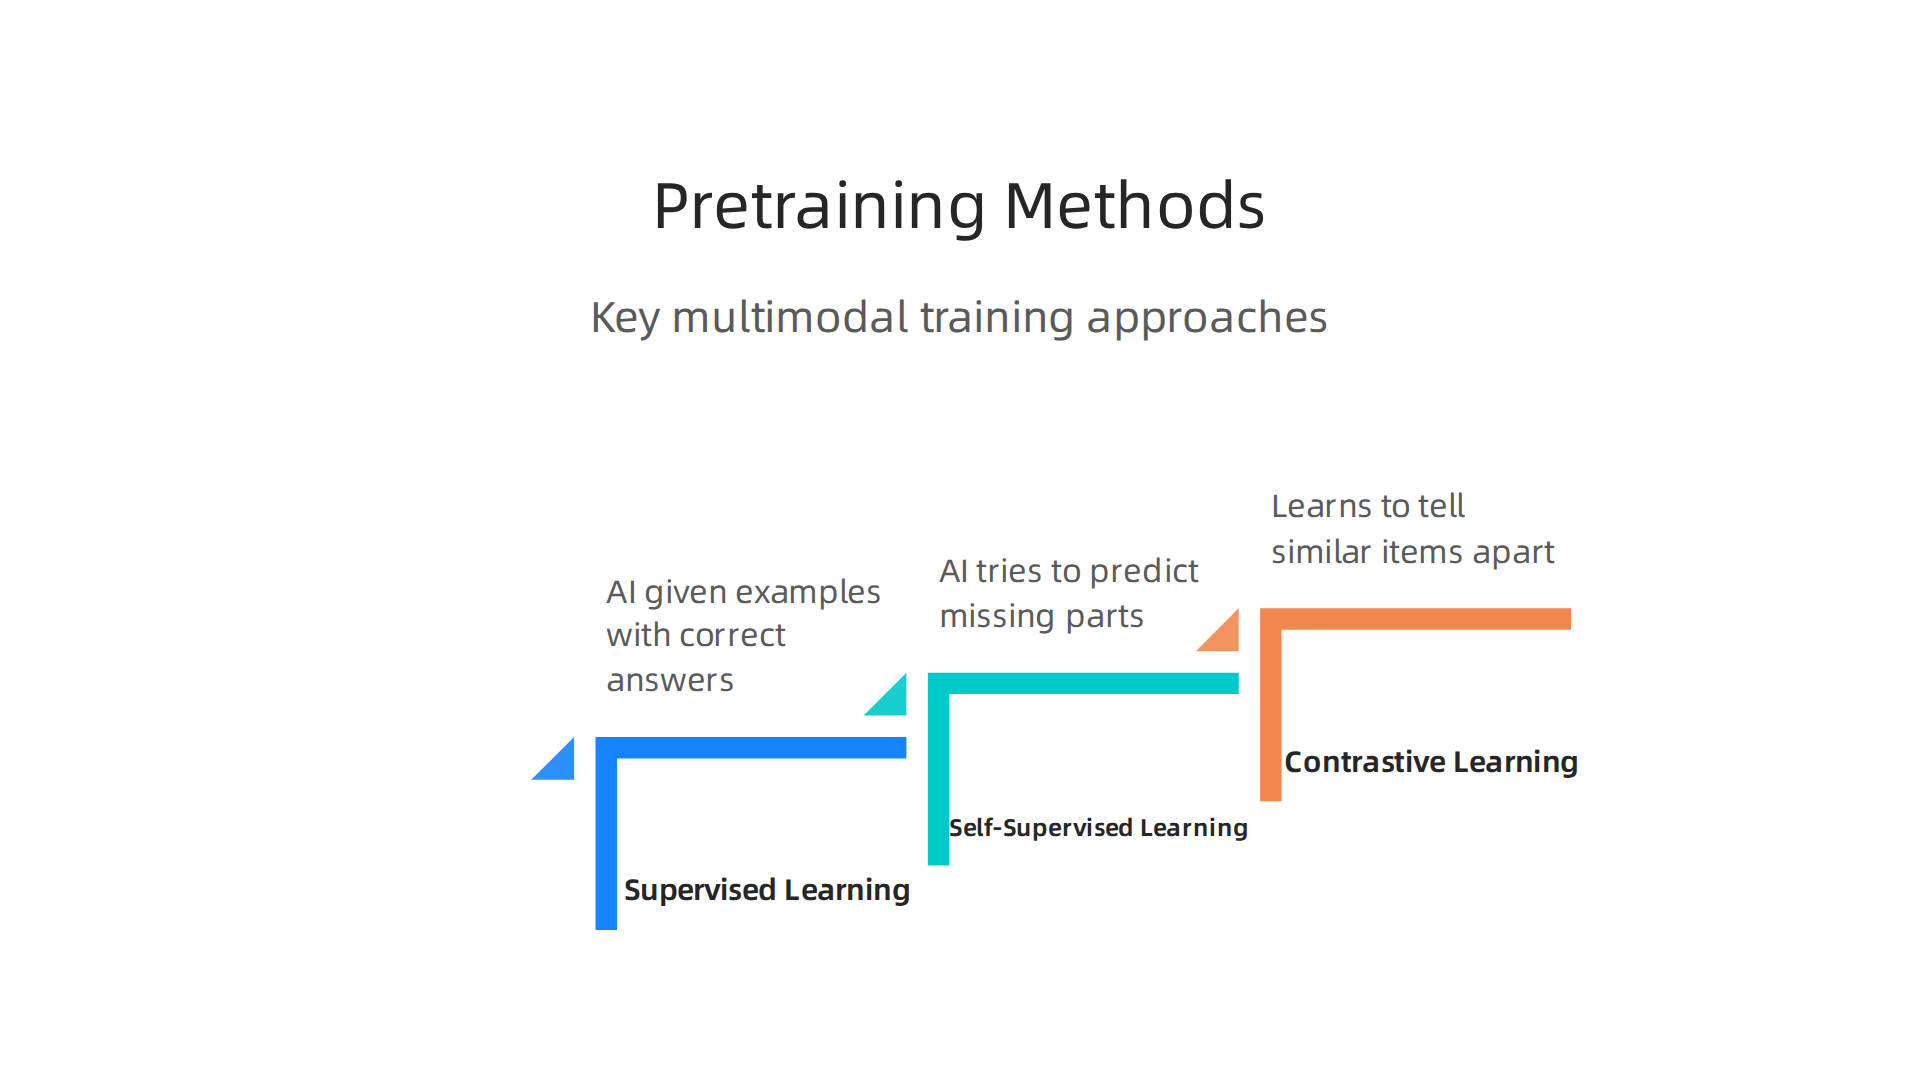
- Supervised Learning: This is the most basic way. The AI is given lots of examples with correct "answers." For instance, it might see a picture of a cat and be told, "This is a cat." With enough examples, it learns to spot cats on its own. While simple, getting enough perfectly labeled data for all types of modalities can be very hard and costly.
- Self-Supervised Learning: This is like giving the AI a puzzle to solve on its own. The AI tries to predict missing parts of the data. For example, it might see a picture with a part covered up and try to guess what’s behind it. Or it might hear a sentence with a word missing and try to fill it in. This way, the AI learns helpful patterns from the data without needing humans to label everything. A key goal during this stage is to align information from different sources, like matching an image to its written description Ask in Any Modality: A Comprehensive Survey on Multimodal.
- Contrastive Learning: This is a very common way to teach multimodal AI to link different types of data. The AI learns by telling similar things apart from different things. Imagine showing the AI a picture of a dog and a text that says "a fluffy brown dog." Then, you also show it many other texts that describe cats, cars, or completely different things. The AI’s job is to figure out which text goes with the dog picture. It gets rewarded for correctly matching the picture to its true description and for correctly saying that other descriptions do not match. This helps the AI understand the connections between words and images, which is vital for contextual AI. These strategies, including contrastive learning, help models learn across different types of data A Survey on Multimodal Foundation Models.
The Building Blocks: Multimodal Datasets
For multimodal AI to learn, it needs huge amounts of data. Think of it as a library filled with different books, pictures, and videos.
- Curation and Scale: These datasets must be carefully gathered and are often massive. Common examples include LAION-400M and LAION-5B, which have billions of image-text pairs A Comprehensive Survey and Guide to Multimodal Large Language. Other datasets like Conceptual Captions or Flickr30k are also used for web-scale pretraining A Survey of 26K Papers (CVPR, ICLR, NeurIPS 2023–2025). Large-scale text-paired data, such as caption data, serves to align different modalities and provide world knowledge for the AI A survey on multimodal large language models.
- Modality Balance: It’s important that the dataset has a good mix of different types of information. If it has too many images and not enough text, the AI might not learn to link them well. Some datasets focus heavily on vision and language A comprehensive survey of Vision-Language Models. You can learn more about how data is prepared for AI by checking out our data annotation tech legitimacy checklist.
- Annotation Types: Often, data is "paired." This means an image comes with a text description, or a video has a spoken narration. This helps the AI connect what it sees or hears with what it reads.
- Bias and Robustness: If the data used for training has biases or mistakes, the multimodal AI will learn those biases too. This can lead to unfair or incorrect results. Ensuring data is balanced and fair is a big challenge in 2026. You can read more about how AI systems might learn unfair behaviors in our article on AI models female bias understanding risks and solutions for leaders 2026.
Learning to Adapt: Transfer Learning
After a multimodal AI model has been pretrained on a huge, general dataset, it has a good basic understanding of the world. This general understanding can then be "transferred" to new, specific tasks.
- Practical Gains: Instead of training a new AI model from scratch for every task, we can take a pretrained multimodal AI and just teach it a little bit more about the new job. This saves a lot of time and computer power. For example, a model pretrained on general images and text can quickly learn to identify specific objects in a factory or understand medical images, even with less new data. This is what helps create the next wave AI applications. Pretraining sets the stage for learning cross-modal relationships, and then fine-tuning adapts these models for specific tasks Ask in Any Modality: A Comprehensive Survey on Multimodal.
Staying informed about these training methods and datasets is crucial for anyone interested in the cutting edge of AI. To keep up with these fast-moving developments, make sure you get clear daily AI updates.
The AI Newsletter Worth Reading
After learning how multimodal AI models get their smarts, the next big question is: how do we actually know if they’re smart? This is where evaluation and benchmarks come in. It’s like giving a student a test to see what they’ve learned, but for multimodal AI, the tests are much more complex because they involve understanding many different types of information at once.
Evaluation and Benchmarks: Measuring Intelligence Across Modalities
Measuring how well a multimodal AI model works is super important. It helps us understand its strengths and weaknesses, and whether it’s truly an example of advanced intelligence. In 2026, researchers use several ways to check these models.
How We Test Multimodal AI
Here are the main ways experts evaluate multimodal AI:
- Task-Based Benchmarks: These are like specific exams. The AI is given tasks that use different types of data, like looking at an image and answering a question about it, or listening to speech and writing it down. A big review of benchmarks for multimodal large language models looked at over 200 ways to test these systems, covering things like understanding and reasoning across different senses A Survey on Benchmarks of Multimodal Large Language Models. Other benchmarks focus on understanding vision, audio, and even code for multimodal AI Multimodal AI Benchmarks 2026: Vision, Audio, Code.
- Zero-Shot or Few-Shot Probing: This tests how well a multimodal AI can handle new tasks it hasn’t specifically been trained on, with very few or no new examples. It shows if the AI has a general understanding that can be "transferred" to new situations. This is key for creating more versatile contextual AI.
- Emergent Behavior Tests: Sometimes, AI models show skills that weren’t specifically programmed or expected. These "emergent behaviors" can be a sign of truly advanced intelligence. Tests try to find these surprising new abilities.
- Safety and Robustness Evaluations: It’s not just about being smart; it’s about being safe and fair. These tests check if multimodal AI models are trustworthy, don’t show unfair biases, and can handle unexpected situations without breaking down. For example, a benchmark called MultiTrust focuses on truthfulness, safety, and fairness in these models A Comprehensive Benchmark Towards Trustworthy Multimodal …. Another approach uses evaluation agents to check claims against web sources and other media for accuracy MiroEval: Benchmarking Multimodal Deep Research Agents ….
The Limits of Today’s Tests
Even with all these tests, current benchmarks have some challenges. They often don’t fully capture how a multimodal AI would understand and act in the real world. Many tests are still too simple or don’t truly match the complex problems people face every day. They might not perfectly show how well a model truly understands the relationships between different types of information, or if it can generalize its knowledge to entirely new, unpredicted scenarios. Sometimes, models perform well on specific tests but fail to generalize when faced with slight changes, which shows they don’t truly understand what they are doing Do Multimodal Foundation Models Truly Generalize? Exposing ….
A Simple Checklist for Choosing a Multimodal AI
If you’re thinking about using a multimodal AI model for your business, here’s a simple checklist to help you decide:
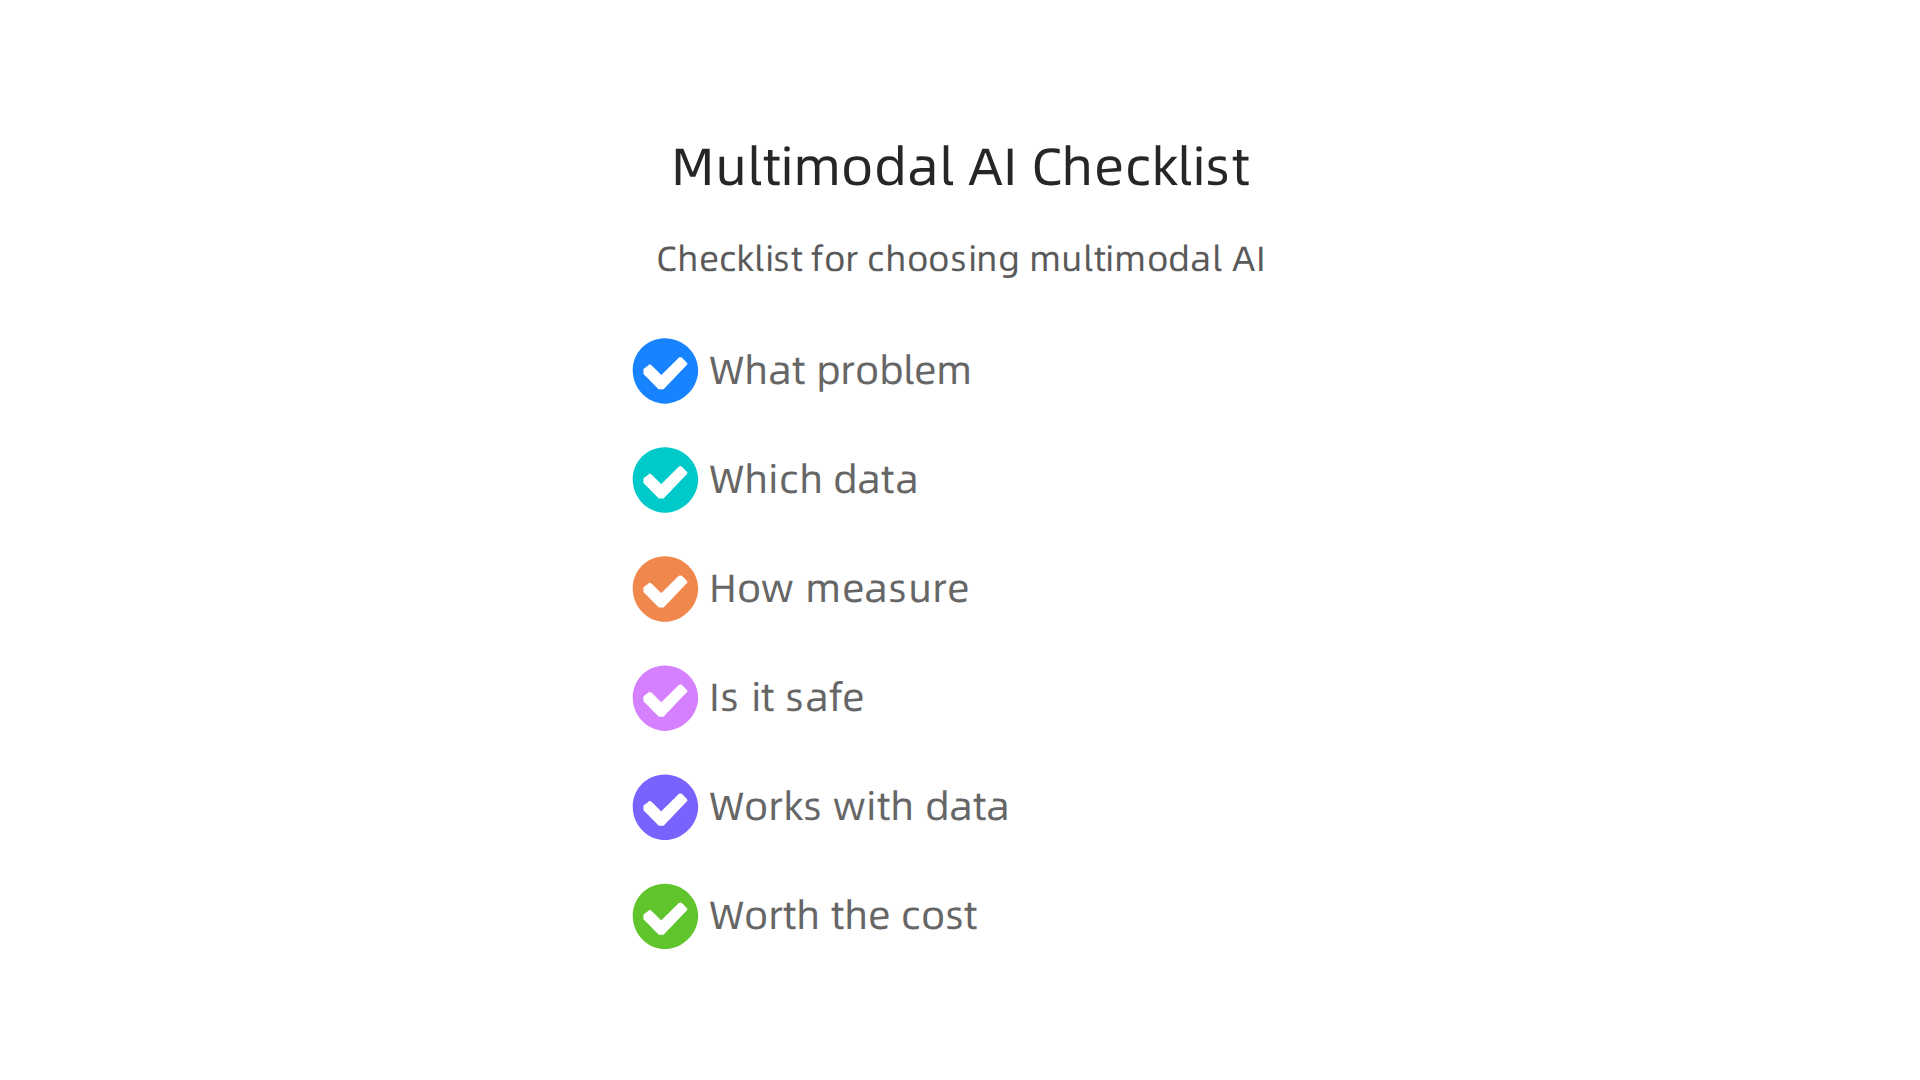
- What problem are you trying to solve? Make sure the AI’s skills directly relate to your needs.
- Which types of data are most important? Does the model handle images, text, audio, or video well for your specific case?
- How will you measure if it’s working? Think about what success looks like and how you’ll track it.
- Is it safe and fair? Check for biases and ensure it won’t cause harm.
- Does it work with your own data? A model might be great in general, but you need to see if it performs well on your specific information.
- Is it worth the cost? Consider the time, money, and effort needed to use and maintain the AI.
Choosing the right multimodal AI means looking beyond simple scores and thinking about how it fits into your real-world goals. For leaders looking to bring AI into their companies, it’s wise to consider comprehensive strategies for adoption. You can learn more in our guide on enterprise AI adoption executive roadmap for strategic business value. Also, understanding how to choose what is the best AI for your specific needs is a crucial step for success, which you can read about in our article on how to choose what is the best AI for your needs.
Even with careful testing, making sure a multimodal AI is truly safe and fair is a big job.
These smart systems can sometimes act in unexpected ways. It’s important to understand these risks, especially as we aim for more advanced intelligence in everyday tools.
What Can Go Wrong with Multimodal AI?
When a multimodal AI works with different kinds of information like pictures, sounds, and text, special problems can pop up:
- Cross-Modal Hallucination: This is when the AI "sees" or "hears" things that are not actually there by mixing up different senses. For example, a model might look at a photo of an empty room but "hear" a dog barking because it linked certain textures in the image with dog sounds it learned before. It’s like imagining things that aren’t real, but across different types of data.
- Modality-Specific Adversarial Attacks: Imagine someone makes a tiny, hidden change to an image or a sound file. These changes are so small that a person wouldn’t even notice them. But for an AI, these tiny changes can completely trick it, making it think something is totally different from what it really is. This is a big challenge for keeping contextual AI safe.
- Biased Associations: AI learns from the data it’s given. If that data has unfair ideas or stereotypes, the multimodal AI can learn them too. For example, if most pictures of doctors in the training data are men, the AI might unfairly assume all doctors are men when it sees a new image. This can lead to the AI making biased decisions across different data types, creating problems that affect people. Learning about how AI models can show unfair biases is important for leaders to understand the risks and solutions, as explained in an article about AI models female bias understanding risks and solutions for leaders 2026.
How to Make Multimodal AI Safer
To deal with these problems, experts use special ways to make multimodal AI more trustworthy:
- Multimodal Calibration: This means making sure all the different types of data (like vision, sound, and text) are understood correctly and work well together. Think of it like tuning an orchestra so all instruments play in harmony. Researchers are always looking at new ways to combine these different data types, often called "fusion strategies," to make sure the AI gets the full, correct picture Multimodal Alignment and Fusion: A Survey.
- Aligned Objectives: This is about making sure the AI’s goals match human values and safety rules, even when it’s processing many kinds of information. It means teaching the AI to focus on being helpful and fair from the very start. Achieving this often involves careful design and training, which can influence how well these models scale and perform, a concept explored in Scaling Laws for Multimodal Foundation Models: A Unified Framework.
- Robust Training: This involves teaching the AI to be strong against tricky attacks and unexpected problems. It’s like giving it a diverse education, showing it many different examples so it doesn’t get fooled easily.
- Human-in-the-Loop Safeguards: Sometimes, the best safety measure is to have people check the AI’s important decisions. This means human experts keep an eye on what the multimodal AI is doing, especially in sensitive situations, to correct mistakes and make sure everything is working as it should.
Rules for Using Multimodal AI at Scale
When big companies use multimodal AI in many places, they need clear rules to keep things safe and fair. These are called governance considerations:
- Auditability: This means being able to look back and understand how the AI made a certain decision. If an AI gives an answer, we should be able to trace exactly which parts of the image, sound, or text led to that answer.
- Provenance: It’s important to know where all the data the AI used came from. Was it good data? Was it collected fairly? Knowing the source helps ensure the AI’s decisions are based on reliable information.
- Monitoring: Once a multimodal AI is being used widely, it needs to be watched constantly. This helps catch new problems quickly, fix biases that might appear over time, and make sure the AI continues to work safely and effectively. Building AI systems for real-world use often involves careful attention to these details, as highlighted in guides for production-grade agentic AI.
Making sure multimodal AI is safe and aligned with our values is just as important as making it smart. By focusing on these challenges and solutions, we can build a future where wave AI and other forms of advanced intelligence truly benefit everyone. If you’re looking for more structured guidance on how to manage AI in your organization, be sure to check out the leaders playbook for AI governance in 2026.
Staying informed about these fast-moving changes in AI is key for anyone involved in technology and innovation.
Discover Daily AI Insights
Want to keep up with the latest in AI, explained simply and clearly?
The AI Newsletter Worth Reading delivers daily updates right to your inbox.
When thinking about using multimodal AI in your business, the question of whether to build your own, buy a ready-made solution, or wait and see is a big one.
It’s not just about how smart the AI is, but also about what makes sense for your company’s money and future plans. Making smart choices here can help you use advanced intelligence to truly grow.
When to Build, Buy, or Wait for Multimodal AI
Deciding on the best path for multimodal AI means looking at a few key things:
- How much money will it make or save? (ROI Drivers): Before jumping in, think about how multimodal AI will help your business. Will it make things faster, improve customer service, or help you create new products? Knowing the direct benefits helps you decide if it’s worth the investment. For example, some companies find great value in using these systems for tasks like understanding customer feedback from different sources, like calls and emails.
- How good is your data? (Data Maturity): Multimodal AI needs a lot of good data to learn. If your company doesn’t have a lot of clean, well-organized pictures, sounds, and text, building your own AI might be very hard. You might need to focus on getting your data ready first. An important step is ensuring responsible AI governance, especially in complex systems that handle various types of information, as highlighted in discussions around Responsible AI Governance in Multi-Modal Enterprise Systems.
- How much will it cost to run? (Compute Economics): Running multimodal AI can use a lot of computer power, which costs money. You need to think about these ongoing costs. Sometimes, using a service that charges you per use is cheaper than setting up all the equipment yourself.
- Does it fit your product well? (Product Fit): Think about how a multimodal AI feature would actually work in your existing products or services. Does it make sense for your customers? Could it truly make your product better? If it’s a perfect fit, it might be time to move forward. To figure this out, it’s helpful to understand the overall AI strategy for executives drive measurable business value.
Building vs. Buying vs. Third-Party Models
Each choice has its own good and bad points:
- Building in-house: This gives you the most control. You can make the multimodal AI exactly how you want it to be. But it costs a lot of time and money, and you need expert people to do it. It’s often best for companies that need very specific or secret AI features.
- Using managed multimodal APIs: These are like renting AI features from another company. They are faster and easier to start with because someone else handles all the hard technical parts. This is often a good choice for smaller businesses or for quickly testing new ideas. You can learn more about picking the right top AI platforms for business growth in 2026.
- Integrating third-party models: This means using an AI model that another company built, but you host or manage it yourself. It gives you more flexibility than APIs but still takes some technical skill to set up and manage. Benchmarking these models is crucial to see if they perform as expected, as covered by a comprehensive survey on Multimodal Large Language Models benchmarks.
Testing with Pilots and MVPs
No matter which path you choose, it’s smart to start small.
- Practical Pilots: Pick a small project to test your multimodal AI idea. This helps you see if it actually works and if your customers like it, without spending too much money or time. For example, test a new AI feature with just a few users first.
- MVP Patterns: An MVP (Minimum Viable Product) is the simplest version of your idea that still offers value. For multimodal AI, an MVP could be a simple tool that understands images and text for a very specific task. This lets you learn quickly and make changes based on real feedback. Testing is crucial, and new ways to do this are always emerging, like benchmarking multimodal deep research agents.
By carefully thinking through these points and starting with small tests, businesses in 2026 can make smart choices about how to bring multimodal AI into their operations. This helps them harness the power of advanced intelligence while keeping risks low.
Want to keep up with the latest in AI, explained simply and clearly? The AI Newsletter Worth Reading delivers daily updates right to your inbox.
The world of multimodal AI is always moving forward, and in 2026, we’re seeing some amazing new directions. It’s like AI is learning to see, hear, and read all at once, making it much smarter. These new ways of working are opening doors for businesses and how we think about the future of advanced intelligence.
Future directions: emergent multimodal capabilities, scaling laws, and the path to general intelligence
One big change we see is how multimodal AI is growing. Think of it like a child learning to speak, then to read, then to understand pictures. The AI models are getting better at handling all kinds of information, not just one type. Scientists are finding that as these models get bigger and are fed more data, their ability to understand different things like text, images, and sounds gets better in a similar way. This idea is called "modality-agnostic scaling," and it means the AI is learning to learn across different senses. Research into this helps us predict how much smarter these AIs can get just by making them larger, as shown in studies on Scaling Laws for Native Multimodal Models.
Another exciting trend is "modular compositionality." This means building complex multimodal AI systems from smaller, smart pieces that work together. Imagine an AI that has one part for understanding voices and another for understanding faces, and these parts can easily be swapped or combined for different tasks. This makes AI more flexible and easier to create for specific business needs. Also, multimodal AI is getting better at using logical rules and existing knowledge, not just what it "sees" or "hears." This is called "integration of symbolic reasoning with perception," and it means AI is starting to understand things more like a human might, using both senses and common sense. This brings us closer to a truly contextual AI.
Looking ahead, researchers are still working on making AI truly intelligent in a general way, like humans are. This means creating AI that can learn new tasks without being specifically trained for them. While we’re not quite there yet, the improvements we’re seeing in multimodal AI are steps on that path. These future capabilities could mean AI that helps us make even better decisions, creates new things we haven’t imagined, or interacts with us in very natural ways. These changes will keep businesses and leaders busy trying to figure out how to best use this new wave AI. Knowing how to choose the right tools and strategies will be key for success. You can explore more about how businesses are planning for these shifts by understanding the importance of an AI strategy for executives drive measurable business value.
For businesses and anyone who makes big decisions, staying up-to-date with these fast changes is super important. The field of AI is always evolving, with new breakthroughs happening all the time in 2026. To make smart choices about using multimodal AI in your work, you need a clear way to keep learning.
Want to keep up with the latest in AI, explained simply and clearly? The AI Newsletter Worth Reading delivers daily updates right to your inbox. This helps you translate new ideas into real plans for your business.
Summary
This guide explains why multimodal AI—systems that combine text, images, audio, video and other data—has become a strategic priority in 2026, and it breaks down how these models are built, trained, evaluated, and governed. You’ll learn the main data types (modalities), pretraining methods like self-supervision and contrastive learning, and the three primary fusion strategies (early, late, and unified approaches). The article covers the datasets and transfer-learning patterns that make multimodal models useful in real tasks, how researchers measure performance with benchmarks and emergent-behavior tests, and practical checks for safety, bias, and robustness. It also guides leaders on when to build versus buy, how to run pilots and MVPs, and what governance and monitoring practices matter at scale. Finally, it outlines future trends—scaling laws, modularity, and steps toward more general intelligence—so readers can make informed, risk-aware decisions about adopting multimodal AI.